Explore how a shared peer-to-peer cache in Kubernetes can streamline AI model sharing across multiple tenants, reducing redundancy and enhancing efficiency.
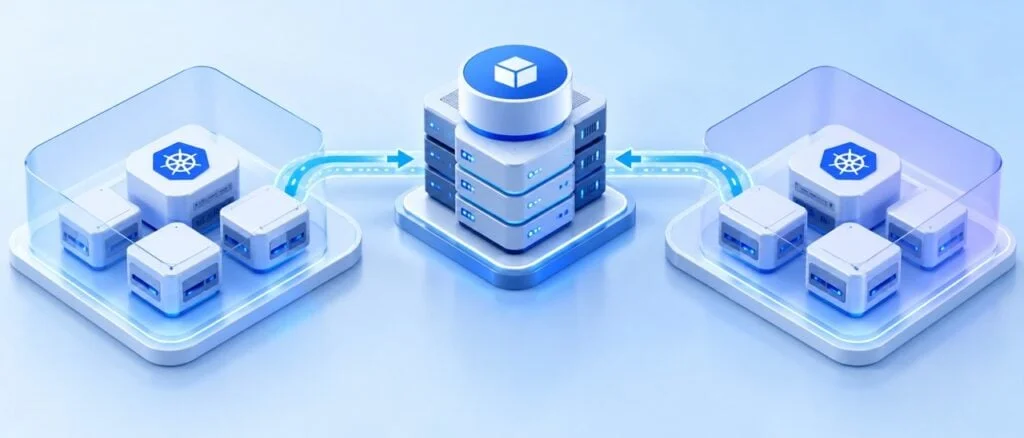
A practical experiment using Dragonfly and vCluster illustrates the efficiency of a platform-managed caching system that enables shared access to AI models across different tenants without compromising security or control.
In multi-tenant Kubernetes environments, each team often gets a distinct API boundary, allowing for autonomy. However, this setup doesn’t prevent redundant requests for large AI model files, leading to unnecessary network traffic and duplicated storage. Instead of each tenant independently fetching the same model, a shared caching solution promises to alleviate this issue.
By implementing a peer-to-peer cache at a platform level, teams can leverage a single model payload efficiently, maintaining operational separation while optimizing resource usage. My recent lab experiment aimed to assess whether a platform-based peer-to-peer cache could effectively distribute AI model files across two virtual clusters without granting excessive privileges to tenant workloads.
Implementing the Cache
The testing environment featured Dragonfly operating in a manager-less state on the host cluster. It utilized seed peers and schedulers to coordinate tasks, while a client DaemonSet was deployed across each node. A critical aspect was that these components were managed exclusively by the platform team, who also controlled the caching mechanism.
Tenant A and Tenant B operated using distinct open-source vCluster API servers designed for scalable, isolated workloads. Their model-download jobs ran as standard non-root Pods, carefully designed not to utilize hostPath, hostNetwork, hostPID, hostIPC or any elevated privileges, ensuring compliance with security best practices. Model downloading relied on the Kubernetes downward API for real-time node IP acquisition, with the model payload routed through a node-local Dragonfly proxy.
Initially, the job sent a HEAD request to Hugging Face to authenticate the model file’s CDN URL. The payload was then downloaded through Dragonfly, where the proxy was configured to strip unnecessary signed query parameters from the cache identity, allowing both tenants to align their requests to the same Dragonfly task for the model payload. Maintaining this cache identity is pivotal to reusability, especially given that URLs can change over time and impact the reuse process.
Results of the Experiment
During the test, Tenant A executed its model retrieval on the host control-plane node, downloading a total of 267,954,768 bytes while generating a SHA-256 checksum verifying the success of the transfer. The operation took approximately 11 seconds to complete.
In contrast, Tenant B was placed on a worker node, which presented a more challenging scenario as the same request couldn’t be sourced from its local cache. Nevertheless, Dragonfly assigned both Tenant A and Tenant B the same task ID. The scheduler then led the second request through the client on the control-plane alongside a seed peer. The logs confirmed that data packets from the existing pieces were delivered to Tenant B, culminating in the same 267,954,768-byte file and identical checksum, but in a quicker span of three seconds. This illustrates the cache’s potential for reusing elements of previously fetched models.
Insights for Platform Engineering
From this experience, a couple of fundamental takeaways emerged. First, treating the cache as a platform service allows for streamlined access while delegating deployment, capacity, monitoring, and updates to the platform team. Second, the integrity of cache identity must be ingrained in the architecture. Proper normalization of signed URLs is essential, particularly in contexts involving private models where additional precautions will be necessary.
The experiment also highlighted critical aspects of logging transfers over speed. While a rapid second download might suggest cache reuse, it does not conclusively indicate whether the source was a local cache, a neighbor peer, or the original source. Importantly, the tested tenants operated with a standard manifests without evaluating potential adversarial scenarios.
Alternative Approaches and Best Practices
There are alternative caching methodologies to consider, including creating registry mirrors on individual nodes, using pull-through caches, or establishing shared persistent-volume caches. The optimal strategy will depend on the type of artifacts, trust hierarchies, storage configurations, and governance around operations. The testing of Dragonfly and vCluster served to evaluate the feasibility of enabling cross-tenant caching while retaining centralized control.
A foundational principle moving forward is to centralize repeated artifact distribution capabilities as a core platform function. This should entail exposing a minimal interface to tenants while ensuring that the actual transfer source is consistently verified. Start with open artifacts and strongly define cache keys, treating other considerations around private model handling, cache invalidation, fault recovery, and resource scaling as unique operational challenges.
Author Bio
Pavan Madduri is a Senior Cloud Platform Engineer at W.W. Grainger and currently serves as the Tech Lead for CNCF’s TAG Workloads Foundation. Actively contributing to the Dragonfly project and recognized as a vCluster Ambassador, he is also a CNCF Golden Kubestronaut.
Discussion
Sign in to join the discussion.